Agents & workflows / PROPOSED CONCEPT
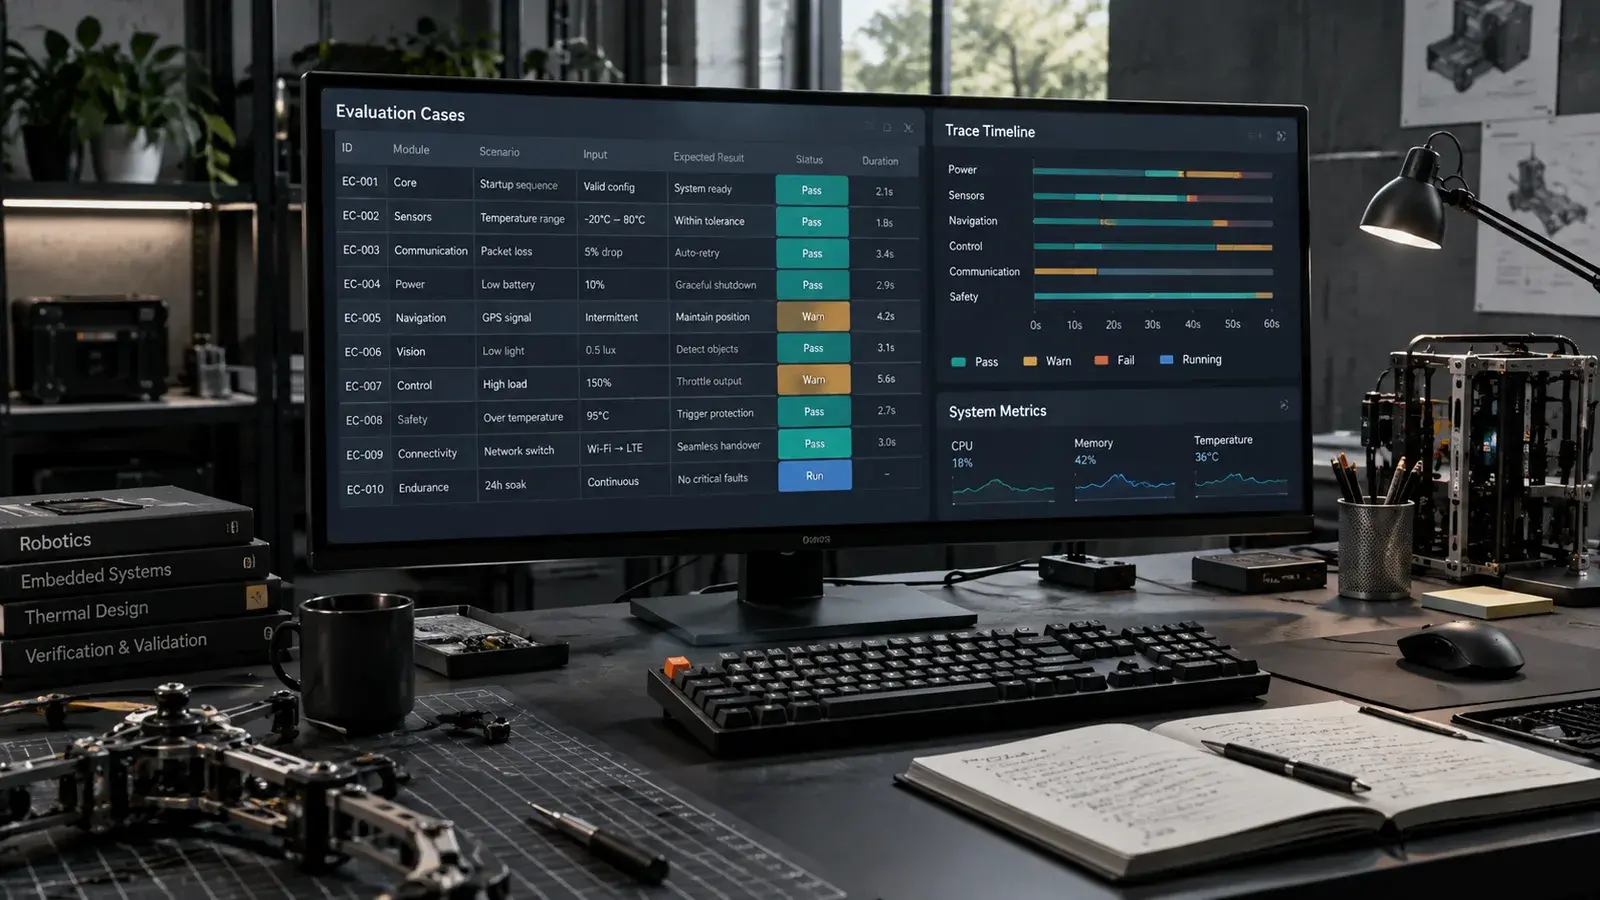
AI evaluation studio.
Know what changed before you release it.
The opportunity
A real need.
A considered response.
A prompt change can fix one example and break another. A repeatable evaluation workspace makes those tradeoffs visible before a new model or workflow reaches users.
DESIGNED AROUND
Product and engineering teams moving AI features beyond a prototype.
The experience
What this could make possible.
Side-by-side configuration runs
Failure clustering
Release review reports
01
Define expected behaviour
→02
Run representative tasks
→03
Inspect the differences
→04
Decide on release
Under the surface
The engineering
behind the experience.
Architecture is a starting hypothesis. Discovery and representative tests decide what belongs in the first build.
POTENTIAL CONNECTIONSModel providersCI pipelineObservability stack
01Architecture to explore+
- Isolated test runners and dataset versions
- Task-specific scoring with human calibration
- Cost, latency and trace collection
02Integration dependencies+
Model providers, CI pipeline, Observability stack. Confirm access, data ownership, update frequency and failure behaviour during discovery.
03Validation and human control+
Evaluate grader agreement, reproducibility and whether tests catch known regressions. A score is evidence about a test set, not proof of performance across all production inputs.
A useful first step
Start small.
Learn something real.
A critical user journey and a small curated regression set covering common and severe failures.
Evidence to look for
Evaluate grader agreement, reproducibility and whether tests catch known regressions.
A boundary to design for
A score is evidence about a test set, not proof of performance across all production inputs.
Proposed scope, not a delivery commitment. Data, permissions, operational constraints and sector requirements need review before implementation.
Connected capabilities
AI Evaluation & OptimisationCloud, DevOps & Platform EngineeringSoftware Quality, Security & ModernisationResearch behind the direction
AnthropicDemystifying evals for AI agents ↗These sources inform technical possibilities. They do not demonstrate a Tomatrix deployment or endorse this proposed product.
From possibility to a conversation
Make this
your starting point.
Add a little context. Preview a practical brief, then keep it for a conversation with Tomatrix.
Built locally from this concept. No AI service is called and nothing is submitted. Please leave out confidential information.
Preview your concept brief
PRODUCT EXPLORATION: AI evaluation studio

Status: Proposed concept — scope and feasibility to be agreed.

Our context:
To be discussed.

Who this could help:
Product and engineering teams moving AI features beyond a prototype.

A useful first pilot:
A critical user journey and a small curated regression set covering common and severe failures.

What to evaluate:
Evaluate grader agreement, reproducibility and whether tests catch known regressions.

Important boundary:
A score is evidence about a test set, not proof of performance across all production inputs.

Integrations to explore:
Model providers, CI pipeline, Observability stack

Concept reference: /products/evaluation-studio
Keep exploring
Related possibilities.
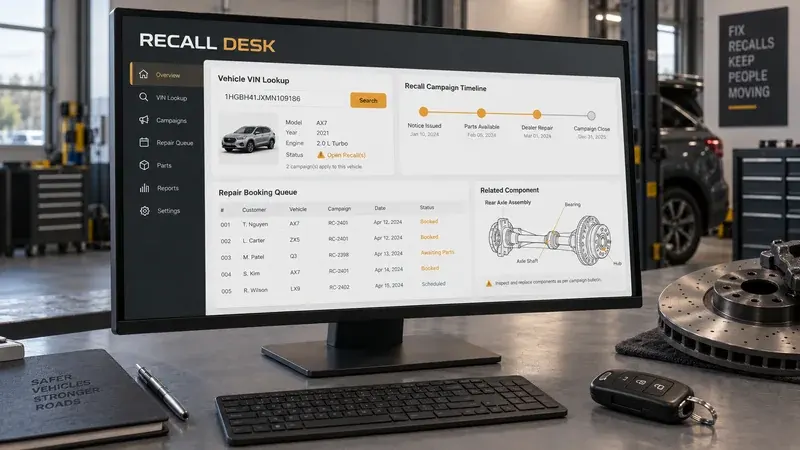
PROPOSED CONCEPT
Recall operations agent ↗
VIN-linked campaign evidence. Repair readiness queue.
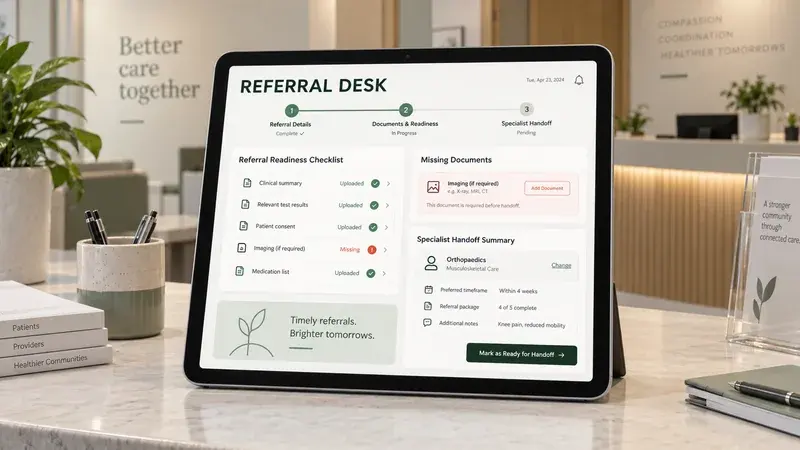
PROPOSED CONCEPT
Referral readiness desk ↗
Referral completeness checks. Source-linked missing items.
PROPOSED CONCEPT
Student support navigator ↗
Policy-grounded guidance. Service request routing.